Base64 Encoding: When to Use It and When Not To
Base64 is useful when binary data needs to travel through text-only systems, but it is not compression, encryption, or a privacy layer. Knowing the difference helps you avoid bloated payloads and false security assumptions.
Base64 turns bytes into text
The main purpose of Base64 is compatibility. It represents binary data using printable characters so the data can fit into JSON, email, HTML, CSS, or URL parameters. The encoded result is usually larger than the original file, so it should be used deliberately.
Use URL-safe Base64 for URLs and tokens
Standard Base64 can include characters that have special meaning in URLs. URL-safe Base64 changes those characters so encoded strings are easier to pass in query parameters, path segments, and token-like values. If a system expects a specific variant, use that variant consistently.
Data URIs are convenient for small assets
A Data URI can embed a small image or file directly into HTML or CSS. This can be handy for demos, tests, icons, and documentation snippets. For large assets, separate files are usually better because they cache more cleanly and keep source documents readable.
Do not treat Base64 as security
Anyone can decode Base64. It should not be used to hide secrets, passwords, private API keys, or sensitive customer data. If data needs protection, use proper encryption, access control, and secret management instead.
Decode before debugging
When debugging encoded data, decode it before inspecting behavior. Many mistakes are simple: accidental whitespace, the wrong character set, missing padding, or a URL-safe string being decoded as standard Base64.
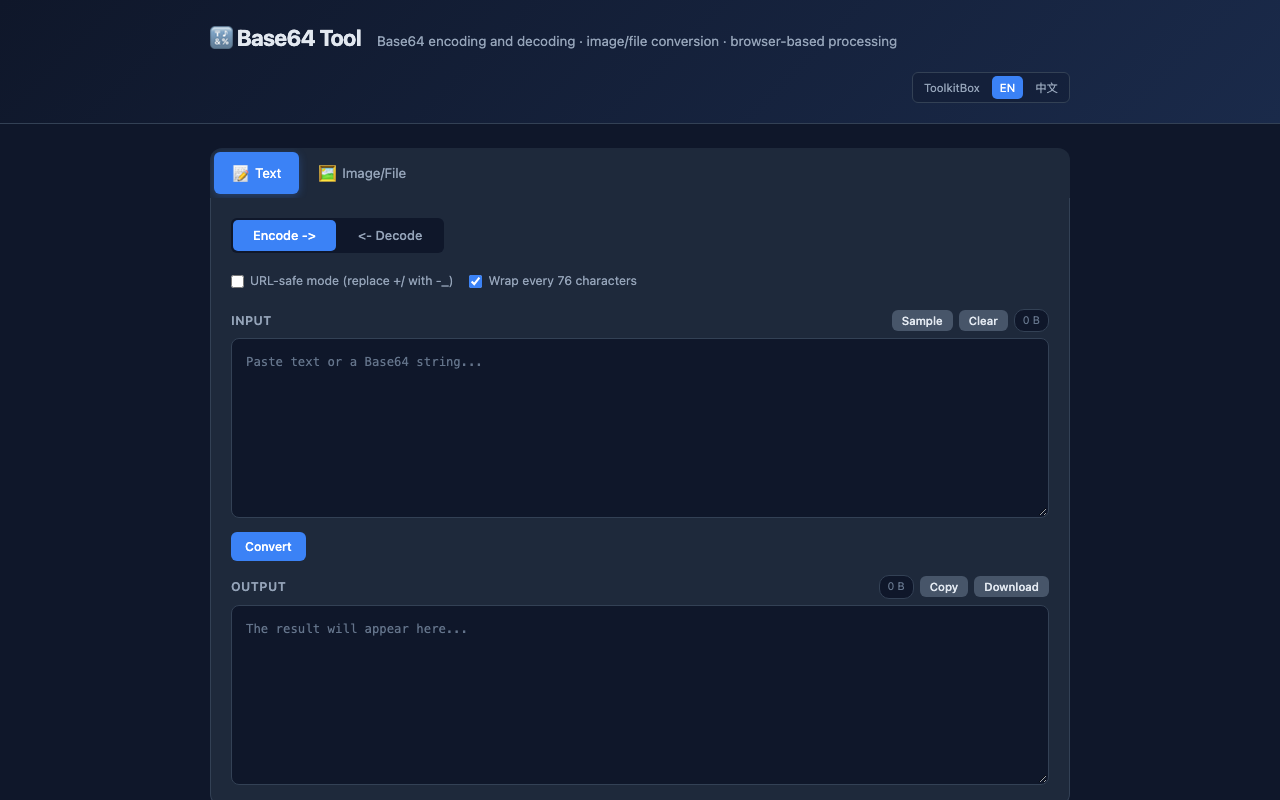
Measure the size tradeoff
Base64 represents every three input bytes with four text characters, before line wrapping or a Data URI prefix. That means the encoded body is roughly one third larger than the binary source. Compression may offset some transfer cost, but it does not make a large embedded asset free. Record the original byte size, encoded character count, and final compressed response before choosing an inline representation.
Text encoding comes before Base64
Base64 works on bytes, not abstract characters. Two applications can display the same text but encode different bytes if one uses UTF-8 and the other uses another character set. In browsers, convert text to UTF-8 bytes explicitly when non-ASCII names, emoji, or CJK characters matter. After decoding, interpret the bytes with the same character set used at the start.
A repeatable round-trip test
- Choose a synthetic sample containing ASCII, one accented character, one CJK character, and an emoji.
- Record the UTF-8 byte length before encoding.
- Encode with the exact variant required by the destination.
- Decode with an independent implementation.
- Compare the resulting bytes with the original bytes, not only the displayed text.
- Test missing padding only if the receiving specification explicitly permits it.
Common failure patterns
- Variant mismatch: a URL-safe string is passed to a strict standard decoder.
- Double encoding: already encoded text is encoded a second time.
- Whitespace: copied line breaks are accepted by one decoder and rejected by another.
- Character-set confusion: decoded bytes are interpreted as Latin-1 instead of UTF-8.
- Secret leakage: a token is logged because the encoded form looks harmless.
- Data URI prefix: the media type and comma are accidentally sent to the Base64 decoder.
Sources and review notes
The alphabet and URL-safe variant in this guide follow RFC 4648. Data URI syntax follows RFC 2397. Samples are synthetic and the verification method is documented on How ToolkitBox tests browser tools.
Try the related tool
Open Base64 Tool to apply this workflow in your browser.